Thursday, April 27, 2023

NFA and DFA - Automata

 Automata theory (also known as Theory Of Computation) is a theoretical branch of

Computer Science and Mathematics, which mainly deals with the logic of computation with

respect to simple machines, referred to as automata.

Automata* enables the scientists to understand how machines compute the functions and solve problems. The main motivation behind developing Automata Theory was to develop methods to describe and analyse the dynamic behavior of discrete systems.

Automata originated from the word “Automaton” which is closely related to “Automation”.

Now, let’s understand the basic terminologies, which are important and frequently used in Theory of Computation.

  • Symbol: Symbol is the smallest building block, which can be any alphabet, letter or any picture.

Alphabets (Σ): Alphabets are set of symbols, which are always finite.

String: String is a finite sequence of symbols from some alphabet. String is generally denoted as w and length of a string is denoted as |w|.


0101010000011111

aaabbbcaac


Note:

A={}

Empty string is the string with 

zero occurrence of symbols, 

represented as ε.


Number of Strings (of length 2) 

that can be generated over the alphabet {a, b} -

                     -   -

1.                     a   a

2.                     a   b

3.                     b   a

4.                     b   b


Length of String |w| = 2

Number of Strings = 4


  • Language: A language is a set of strings, chosen from some Σ* or we can say- ‘A language is a subset of Σ* ‘. A language which can be formed over ‘ Σ ‘ can be Finite or Infinite.

L -> set finite ,infinite


 Finite state automata 


Finite Automata(FA) is the simplest machine to recognize patterns.

A Finite Automata consists of the following :

Q : Finite set of states.

Σ : set of Input Symbols.

q : Initial state.

F : set of Final States.

δ : Transition Function.

Formal specification of machine is

{ Q, Σ, q, F, δ }.


FA is characterized into two types:


1) Deterministic Finite Automata (DFA)

DFA consists of 5 tuples {Q, Σ, q, F, δ}. 

Q : set of all states.

Σ : set of input symbols. ( Symbols which machine takes as input )

q : Initial state. ( Starting state of a machine )

F : set of final state.

δ : Transition Function, defined as δ : Q X Σ --> Q.

In a DFA, for a particular input character, the machine goes to one state only. A transition function is defined on every state for every input symbol. Also in DFA null (or ε) move is not allowed, i.e., DFA cannot change state without any input character.

For example, below DFA with Σ = {0, 1} accepts all strings ending with 0.

DFA1-300x208

One important thing to note is, there can be many possible DFAs for a pattern. A DFA with minimum number of states is generally preferred.


2) Nondeterministic Finite Automata(NFA)

NFA is similar to DFA except following additional features:

1. Null (or ε) move is allowed i.e., it can move forward without reading symbols.

2. Ability to transmit to any number of states for a particular input.

However, these above features don’t add any power to NFA. If we compare both in terms of power, both are equivalent.

Due to above additional features, NFA has a different transition function, rest is same as DFA.

δ: Transition Function

δ:  Q X (Σ U ε ) --> 2 ^ Q.

As you can see in transition function is for any input including null (or ε), NFA can go to any state number of states.

For example, below is a NFA for above problem

NFA

One important thing to note is, in NFA, if any path for an input string leads to a final state, then the input string accepted. For example, in above NFA, there are multiple paths for input string “00”. Since, one of the paths leads to a final state, “00” is accepted by above NFA.


Some Important Points:

1. Every DFA is NFA but not vice versa.Justification:
Since all the tuples in DFA and NFA are the same except for one of the tuples, which is Transition Function (δ)
In case of DFA

δ : Q X Σ --> Q

In case of NFA

δ : Q X Σ --> 2Q


  • Now if you observe you’ll find out Q X Σ –> Q is part of Q X Σ –> 2Q.

    In the RHS side, Q is the subset of 2Q which indicates Q is contained in 2Q or Q is a part of 2Q, however, the reverse isn’t true. So mathematically, we can conclude that every DFA is NFA but not vice-versa. Yet there is a way to convert an NFA to DFA, so there exists an equivalent DFA for every NFA.

2. Both NFA and DFA have the same power and each NFA can be translated into a DFA.

3. There can be multiple final states in both DFA and NFA.

4. NFA is more of a theoretical concept.

5. DFA is used in Lexical Analysis in Compiler.


Conclusion:

For alphabet {a, b} with length n, number of 

strings can be generated = 2n.

  • Note – If the number of Σ’s is represented by |Σ|, then number of strings of length n, possible over Σ is |Σ|n.

Powers of ‘ Σ ‘ :
Say Σ = {a,b} then
Σ0 = Set of all strings over Σ of length 0. {ε}
Σ1 = Set of all strings over Σ of length 1. {a, b}
Σ2 = Set of all strings over Σ of length 2. {aa, ab, ba, bb}
i.e. |Σ2|= 4 and Similarly, |Σ3| = 8
Cardinality : Number of elements in a set, which is basically |Σ|n.


Σ* is a Universal Set.

Σ* = Σ0 U Σ1 U Σ2 ..........

   = {ε} U {a, b} U {aa, ab, ba, bb}

   = .............   //infinite language.


Sunday, August 21, 2022

Setting Up Your Quora Profile

 Quora's main function is straightforward: you can use the site to ask questions and receive answers, or you can answer questions. 


They range from general questions like How did you change your life? and What is a life hack that you think everybody should know? to industry-specific, technical questions like What are the most useful Shopify apps? and What is the newest innovation in online learning?. The latest study revealed that the platform has close to half a million topics.


The largest worry with crowd-sourced information, however, is if the information provided is genuinely factual, or at the very least, totally correct. Fortunately, many of these issues are alleviated by the fact that industry experts frequently respond to questions on Quora.


Becoming a Quora user is fast, easy, and FREE


Steps for setting up the Quora profile for success:


  1. Go to www.Quora.com


To create a Quora account, you'll need an email address or a Facebook account. You'll be brought to the Quora Account Sign in screen if you've never logged in before (see above image). If you want to access the signup choices, log out of your current account.


  1. Choose from Google, Facebook or sign up with email


Quora setting up

A Quora account can be created in one of three ways. You'll be sent to a different window for each option.


Step 1 – Continue with Your Google Account


If you choose the Google account option, you will join up with Quora using your

Gmail account. A popup will appear, requesting that you sign in. Your Quora account

will be established automatically once you sign in. Continue to step 3 for more

information.


Step 2 – Continue with your Facebook account

You may also sign up for Quora using your Facebook account. If you select this

option, you will be directed to the Facebook website, where you must log in.


After logging into your Facebook account, click the blue box to allow Quora access to

your Facebook profile image and email address.


Your Quora account will be established immediately after you grant permission to

Quora. You could be asked to invite your Facebook friends after that. You have the

option to do so or not. Continue to step 3 for more information.


Step 3 – Sign up with email


Signing up using your email address is the third option. You can still use your Gmail

account for this option, but it will no longer be linked to Quora. A window will appear,

prompting you to enter your name and email address. A verification code will be

emailed to your email when you click next.

A window will appear, prompting you to enter your name and email address. A

verification code will be emailed to your email when you click next.


  1. Select at least 10 topics to follow.

After you've signed up, a modal window will appear, asking you about your

interests and   offering you a variety of themes to choose from. Choose at least

ten topics that are connected to your blog's theme. If you think the themes are too broad, it's fine to choose additional, seemingly unrelated topics; you can always edit them later.


  1. Complete your bio.

Now is the moment to finish your bio! To have a more tailored feed, reach out to like-minded users, and let other users know that you're an authority on any given topic, you want to be as thorough as possible.


You can add your professional credentials as well as educational credentials. Your professional background persuades Quora users that you are knowledgeable. It will also aid in the creation of your feed.


Your educational experience will help you gain credibility on Quora, especially if you'll be answering questions in your field of study. When creating an account, don't forget to complete this step.

Quora will be able to serve you with geo-specific material if you include the areas you've lived and are now living on your profile.


Take a few minutes to set up a brief bio about yourself. It can be brief and to-the-point, or you can write a complete paragraph about yourself, your background, and your ambitions to give depth to your responses. This can take some time, but it'll be well worth it once you're on the first page! 5. 5.Join Quora as a user.

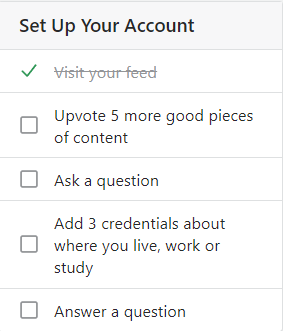
Now that you have a Quora account, it's time to start answering questions and become an active Quora user. Quora can assist you with this by providing you with a checklist of more than three distinct ways to get started! Begin by scrolling through your feed and upvoting material you enjoy.


You can join Quora Spaces and follow Quora users in your chosen topic. Quora spaces are similar to Facebook Groups in that they allow you to join like-minded people in discussing specific topics in a more private and engaging environment.


It's time to accomplish what you came to Quora for – answering questions — once you've completed their step-by-step process. You will be given an initial list of generic questions to answer by Quora.


The majority of these questions are life-related and may be answered in depth by almost everyone. You will be asked more specific questions as time goes on, ones that are more tailored to your niche, skill, and knowledge. This is Quora informing you that they are looking for your own answer.


Tuesday, May 18, 2021

Finite Automata - NFA and DFA


Finite Automata - is the simplest machine to recognize patterns.


A finite Automata consists of :


   Q : Finite set of states.

Σ : Set of Input Symbols.

q : Initial State

F : Set of Final States

δ : Transition Function

Formal specification of machine is {Q, Σ, q, F, δ}

FA is characterized into two types:

Deterministic Finite Automata(DFA)

Non Deterministic Finite Automata(NFA)

Deterministic Finite Automata

DFA consists of 5 tuples {Q, Σ, q, F, δ}. 

Q : set of all states.
Σ : set of input symbols. ( Symbols which machine takes as input )
q : Initial state. ( Starting state of a machine )
F : set of final state.
δ : Transition Function, defined as δ : Q X Σ --> Q.

In DFA, when an input character is given the machine goes to one state only.
A transition function is defined on every state for every input symbol.

ALso in DFA null (or ε) move is not allowed.

 i.e., DFA cannot change state without any input character.

For example, below DFA with Σ = {0, 1} accepts all strings ending with 0

2) Nondeterministic Finite Automata(NFA)


NFA is similar to DFA except following additional features:
1. Null (or ε) move is allowed i.e., it can move forward without reading symbols.
2. Ability to transmit to any number of states for a particular input.

Due to above additional features, NFA has a different transition function, rest is same as DFA.

δ: Transition Function
δ:  Q X (Σ U ε ) --> 2 ^ Q. 

As you can see in transition function is for any input including null (or ε), NFA can go to any state number of states.


Some Important Points:

    1. Every DFA is NFA but not vice versa.
  • Justification:
    Since all the tuples in DFA and NFA are the same except for one of the tuples, which is Transition Function (δ)
    In case of DFA
    δ : Q X Σ --> Q
    In case of NFA
    δ : Q X Σ --> 2Q
    

    Now if you observe you’ll find out Q X Σ –> Q is part of Q X Σ –> 2Q.

    In the RHS side, Q is the subset of 2Q which indicates Q is contained in 2Q or Q is a part of 2Q, however, the reverse isn’t true. So mathematically, we can conclude that every DFA is NFA but not vice-versa. Yet there is a way to convert an NFA to DFA, so there exists an equivalent DFA for every NFA.

2. Both NFA and DFA have same power and each NFA can be translated into a DFA.
3. There can be multiple final states in both DFA and NFA.
4. NFA is more of a theoretical concept.
5. DFA is used in Lexical Analysis in Compiler.


Tuesday, August 25, 2020

Different types of scoring matrix

 We know how to calculate scoring matrix. There are different types of scoring matrix based on the concept of frequency of occuring of certain amino acids within the biological sequences, there are multiple strategies to compute this frequencies. Towards that we are going discuss about PAM Scoring Matrix.

The alignments are scored very nicely if we use an empirical scoring method. That is a scoring matrix based on experimental observed frequencies of amino acids, there are multiple types of matrix but the main matrices are PAM and BLOSSUM matrix.

So first we will discuss about PAM Scoring Matrix

PAM - Point Accepted Mutations Matrix.

Point accepted Mutation Matrix is a substitution of one amino acid by another such that the protein stays conserved.

Note: There are cases where the substitution of one amino acid by another amino acid changes protien, but in PAM those mutations(substitutions) are considered where the overall function of the protein stay conserved or stays the same.

PAM Unit:

PAM unit is the time in which 1% of amino acids in a sequence undergo accepted mutations and this will be PAM1.

Since sequences are long and there are a multiple neucliotides or amino acids in the sequences, then 1% of sequences changed does not necessarily mean that a 100% PAM will have 100% variation in the sequences, because the same site can be changed more than one time, ie. if the same site mutated multiple times then the entire sequence may not be changed for the entire protien.

To understand this we will consider a graph, in which the sequence difference and PAM Distance are compared


Figure 1:

In this a PAM Distance of 100 dosen't mean that there is 100 percentage change in the sequence, because one site on mutation will further mutate and will be accumulated with multiple mutations.

So the experimental data shows if you have a 100 PAM Distance then only 55 to 60 percentage of the sites in the protein are actually mutated. So for the 85 % variations the PAM Distance will increase over than 300.


figure 2

In figure 2 the value of k is 20 (ie 20 amino acids) you can calculate the PAM 1 by using this calculation.


If you want to find PAM 2 then just square the PAM1

similarly if you want to find PAM'n' then multiply PAM 1 'n' times.


If you multiply PAM 1 by 250 times then PAM 250 matrix will get the subsitution matrix like this


In conclusion PAM Matrixes are scoring matrixes that are used for comparing sequences. We can compute PAM 1, PAM2 etc upto PAM 250 or more and PAM 120 is considered as optimal scoring matrix


Deriving Scoring Matrix

 We know the importances of Scoring Matrixes, Instead of scoring the same score for all matches or mismatches the scoring matrix allow us to have a flexible scoring scheme. Flexible scoring scheme means substitution of specific amino acids by others is scored differently and similarly for matches and mismatches all of the scores are computed based on the frequency of occurance of these amino acids in similar protein sequnces.

How do we arrive the Scoring Matrix?

We compare biological sequences by aligning them or we call it as Pair wise sequence alignment, and during this alignment we rank the matches between sequences using scoring matrix


By looking at the chemical properties of amino acids we can see which amino acid will ge higher score

and which amino acid substitution get a lower score.


In the above figure 20 amino acids are listed and colorful diagram shows the chemicalproperties as well.

For example,the green ones are the polar amino acids the brown ones as indicated are the charged amino acids, there are lots of hydrophobhic amino acids, hydroxilix amino acids, tiny amino acids( basically very small amino acids), small amino acids, acidic amino acids and basic amino acids. These are the different properties of amino acids that make them get substituted or conserved within the protein sequences


Figure2

Now let's consider the report generated by Robinson and Robinson several years ago.

In this the columns states that each amino acid has a specific frequency of occurance on average, that means Alanin has an average occurance of 0.078 on a scale of 1 similarly Argenine etc.

Now let's discuss how did they compute frequency, for that similar protein sequences was considered and counted the occurance of each amino acid an normalised it between zero and one.

Example: 

Consider the case of three amino acids from the 20 amino acids inorder to simplify the problem. And also consider a small protein comprising of 4 amino acids.


Next count how many A's are converted into A, how many A's are converted into B's, how many A's are converted into C's,how many B's are converted into B's, how many B's are converted into C's, and how many C's are converted into C's


The observed frequencies  fij in fig.5 shows the frequencies of ocuurance in the conversion, there are total 60 conversion and if you consider C to C then it is 2/60


fig.6

The C in sequence no.3 is converted to another C in sequence 5 likewise the C in sequence no.2 is converted to another C in sequence no.3 thus it got the count as 2 out of 60. 

If we consider B to B then 6 B's are converted to other B's  then we will get 6 over 60.


figure 7

Likewise others are also calculated.

Here fij denotes the conversion of one amino acid to another


figure 8

In fig.8 we can the observed frequencies fi which will be the observed frequencies of the entire set of proteins, ie the frequencies of each amino acids. If we consider the case of C the value 4 over 24 means the entire C in the particular sequence.


figure 9

Now considering


Here S(i,j) means for Scoring matrix any entry can be computed for example i, j by computing log to the second base of fij over pij's. So pij means the frequency of occurance of amino acids if they are the same ie pij = fifi if i equals to j , if they are different means i is not equal to j then pij equals to 2 times fi and fj.


Likewise pij is computed . 

And you can see 2sij is also computed 


And finally scoring matrix is obtained .


We can see in scoring matrix each element is an integer, so all elements in Sij into integers.

Finally the Scoring Matrix for the 3 amino acids is obtained.

In conclusion based on the frequency of certain amino acids we can compute the scoring matrix and then we can use them to compare sequences that are given for comparisons


Monday, August 24, 2020

Scoring Matrix in Bioinformatics

In Pairwise Sequence Alignment or comparison of two sequences as a pair is essentialy to compare their constitution. The constitution can be from amino acis or neucliotides. When  You want to compare these two sequences then you want to score the result.But in the reallife due to the evolutionary pressures the rate of replacing the different amino acid by others is different.So therefore it is necessary to incorporate the variable propencity of replacement or substitution by suitable scores.In this goal we are helped by Scoring Matrix.

We will see what are the scoring matrixes, how we will build scoring matrixes and how we can use them in the alignment process.

Introduction of Scoring Matrix

 
An amino acid can be replaced by another amino acid based on their chemical ,physical and other special properties. so if two amino acids have same chemical behaviour then there is a high chance for their substitution during evolution, However if there is totaly different properties then there is  very low chance of such an amino acid replaced by another amino acid


So the scoring Matrixes they are variable or flexible in scoring such substitions and therefore they have the substition for each amino acid scored differently, ie scoring matrixes have substitution value of each amino acid in a unique way.

How to build Scoring Matrix?


Consider the protein sequences that are there in nature, find protein sequences that are similar to each other and homologous to each other, so once we isolated the set of similar protein sequences then we see which amino acid in one sequence is substituted with which amino acid in the other sequences.In this way we build a frequency list of amino acid that is frequently an amino acid is substituted by another amino acid,

Scores in the Scoring Matrix


So the scoring Matrix by looking at such frequencies may contain a +ve value ie a very easy transition or substitution from one amino acid to another , -ve value which means a rare substitution and may be a zero  as well.

Here is an example of a protein called Ubiquitin


List of ubiqutins are shown from humans, chimps, mouse etc. and their sequences have been aligned with each other as we can see some of the amino acids are raely substituted while some others are completely conserved while some other amino acids are changed.


So what we do in such a frequency count is to apply a formula

Here S will be the Scoring Matrix
         a  will be he first amino acid
         b  will be the second amino acid
So subtitution a by b will be scored by multiplying some constants

 by the log of this ratio 

Pab is the probability of amino acid 'a' substituted by amino 'b' where a nd b can be any two amino acids.
fa and fb  is the frequencies of amino acids a and b

So by computing the S for a,b, and if you vary a and b to all the amino acids that is 20 amino acids you can arrive at the scoring matrix.

Let us consider a scoring matrix


Consider the negative score -5 when D is substituted by W or zeros when S is substitued by D Q G. The diagonal indicated by red line shows very high scores specially if C is substituted by another C the score is substituted by 13, which means C is mostly conserved.

So in Conclusion, A postive value  like +1,+5 has been assigned for match, similarly -10, -2 for mismatches for all the amino acids the scoring matrixes selectively score or score differently for each amino acids depending on their chemical and physical properties which are reflected in their frequency of occurance.